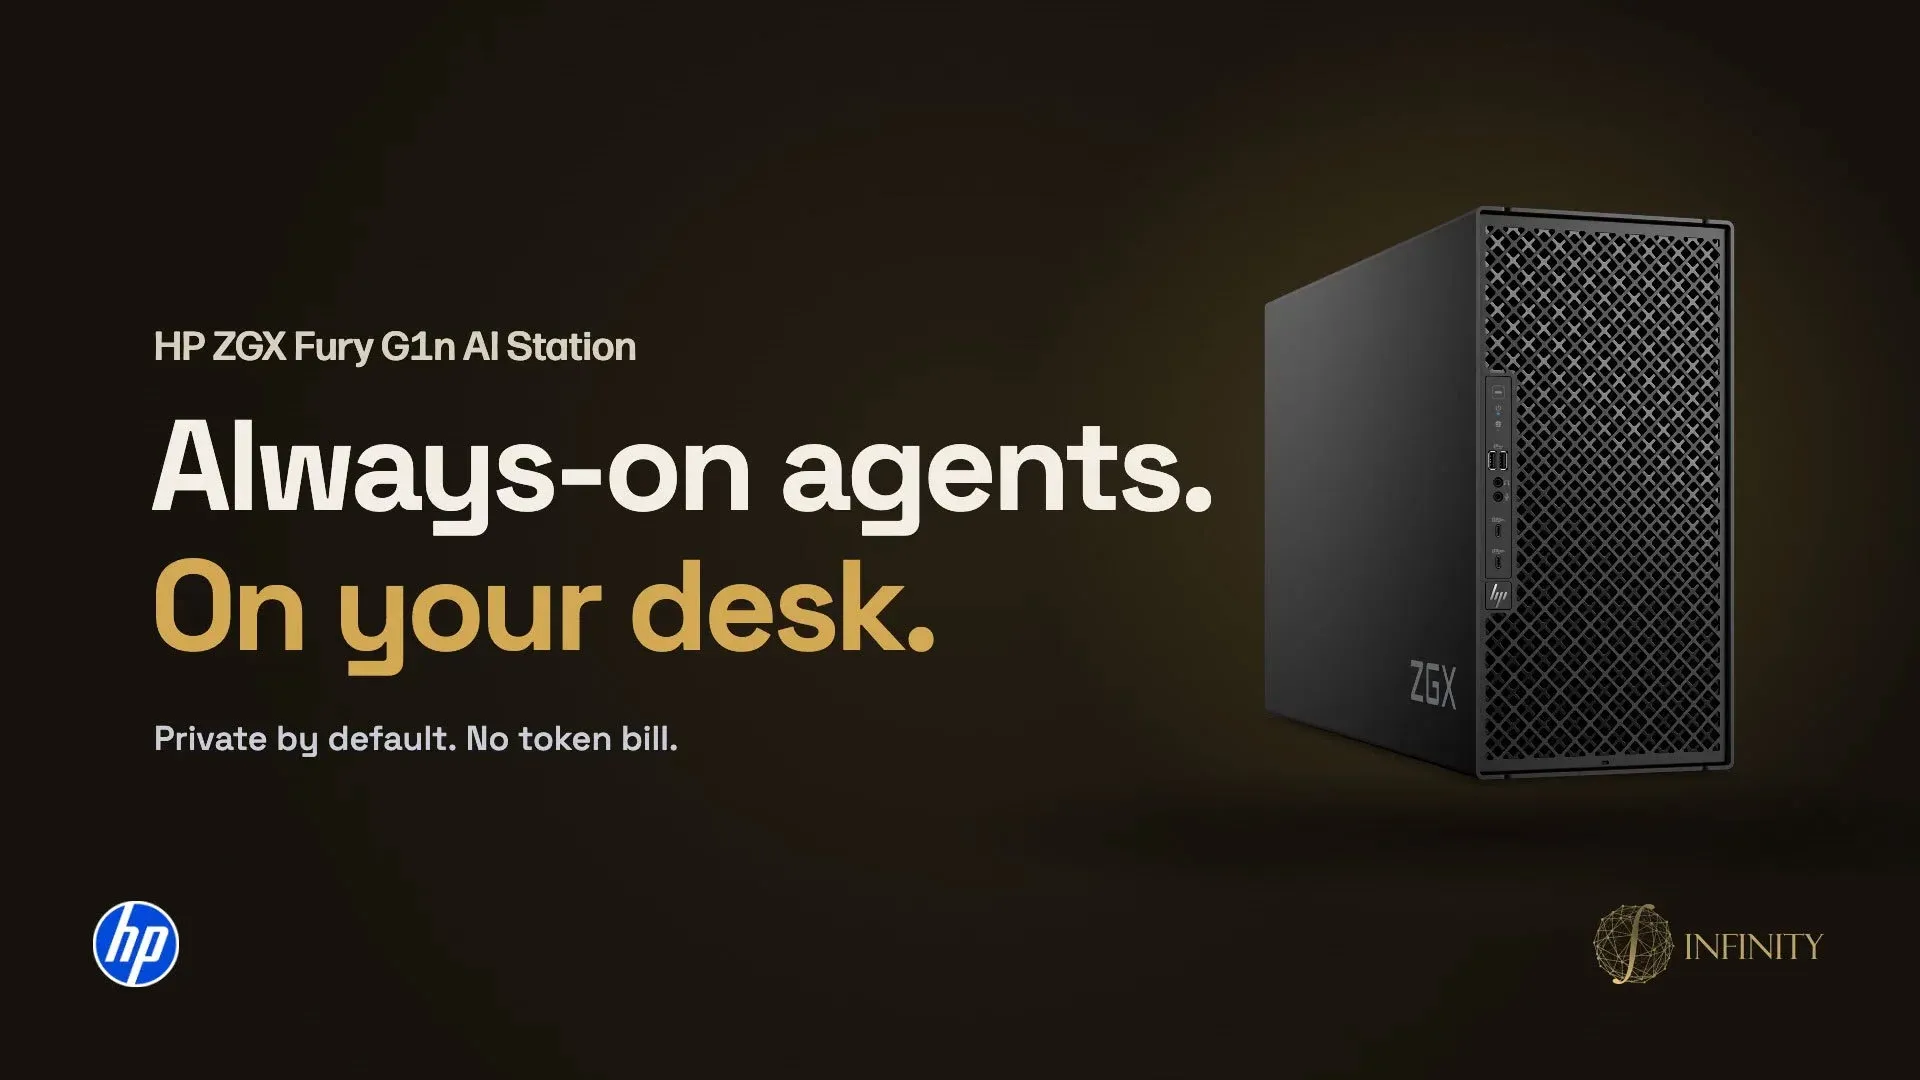
Maximizing the efficiency of existing silicon is becoming a primary strategic imperative as enterprise AI spending shifts from model training toward high-intensity inference. Infinity and HP Inc. are positioning themselves at this intersection, announcing a collaboration that reportedly doubles concurrent AI workload capacity and overall token throughput on the HP ZGX Fury desktop station. This performance gain was achieved using the NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip running the NVIDIA Nemotron 3 Super model. By applying Infinity’s automated software optimization to HP’s hardware, the companies aim to demonstrate that significant compute gains can be realized through software-layer refinements without requiring hardware upgrades. This development arrives as global AI inference spending is projected to overtake training spending this year, reaching an estimated $23.3B.
Optimizing the HP ZGX Fury via Infinity Auto Research
The technical core of this collaboration involves using Infinity’s "Auto Research" capabilities to optimize the inference stack on the HP ZGX Fury, a Z AI station built on the NVIDIA DGX Station platform. The HP ZGX Fury is designed as a rack-mountable, office-deployable unit, intended to provide shareable AI compute for developer teams or multiple simultaneous users. In testing, the teams achieved approximately 2X concurrent requests while maintaining a defined responsiveness threshold. This means the same hardware can serve twice the amount of AI work compared to the baseline configuration.
To reach these results, Infinity’s engineering team implemented optimizations across the inference stack, utilizing techniques from vLLM, NVIDIA TensorRT-LLM, and SGLang, alongside proprietary methods. The company claims this initial performance jump was delivered in under 24 hours of engineering work. This speed of optimization is a central pillar of Infinity’s value proposition; the company uses an autonomous AI agent called Ignition to write and test low-level compute kernels, a process that traditionally requires months of manual engineering. By automating this layer, Infinity seeks to bridge the gap between raw silicon capability and production-ready inference performance.
Scaling Local AI Infrastructure for Enterprise Inference
As organizations move toward agentic AI—which requires multi-step, autonomous execution—the demand for compute-intensive inference is rising. Gartner forecasts that worldwide spending on AI-optimized cloud infrastructure will grow 96% in 2026 to reach $42B. This shift highlights a growing need for efficient local and edge compute solutions that can handle high-concurrency workloads. The HP ZGX Fury is positioned to address this by allowing multiple users to run inference simultaneously or enabling developers to fine-tune models in parallel on a single device.
The collaboration underscores a broader industry trend where the bottleneck for AI adoption is shifting from hardware availability to software optimization. While NVIDIA’s CUDA ecosystem provides a significant head start for established chips, new hardware often struggles to reach theoretical peak performance due to immature software stacks. Infinity is attempting to solve this by providing a software layer that makes any AI chip "inference-ready" in days rather than years. By integrating this with HP’s high-performance desktop hardware, the partnership suggests a path for enterprises to maximize the return on their AI investments through improved hardware utilization.
Key Takeaways
- Infinity and HP achieved a 2X increase in concurrent AI workloads and token throughput on the NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip.
- The performance gains were realized on the HP ZGX Fury, an office-deployable AI station based on the NVIDIA DGX Station platform.
- Infinity utilized its proprietary optimization technology to deliver these results in less than 24 hours of engineering work.
TechInsyte's Take
In our view, this collaboration signals a critical pivot in the enterprise AI lifecycle: the era of "brute force" hardware scaling is being supplemented by a "software-defined efficiency" era. As inference spending begins to outpace training, the ability to squeeze more utility out of existing silicon becomes a massive financial lever for CIOs. The fact that Infinity claims to have doubled throughput in under 24 hours suggests that the traditional bottleneck—the months-long cycle of manual kernel optimization—is being disrupted by autonomous AI agents. For the enterprise, this means the "time-to-value" for new AI hardware could shrink significantly. However, the long-term success of this approach depends on whether these automated optimizations can maintain stability and security at the scale required for mission-critical, agentic AI workflows.
Questions & Answers
How does the HP ZGX Fury support multi-user AI environments?
The HP ZGX Fury, based on the NVIDIA DGX Station platform, offers a rack-mountable and office-deployable design that enables multiple users to run inference simultaneously or allows developer teams to perform parallel experimentation and fine-tuning on a single unit.
What specific technical methods did Infinity use to increase throughput?
Infinity’s engineering team applied optimizations across the inference stack by combining techniques used in vLLM, NVIDIA TensorRT-LLM, and SGLang with their own proprietary work to increase concurrency without degrading per-user responsiveness.
Why is the shift from AI training to AI inference significant for infrastructure planning?
As AI moves toward agentic, autonomous execution, inference becomes more compute-intensive. With global inference spending expected to reach $23.3B this year, surpassing training spending, organizations must prioritize the utilization and performance of their deployed inference infrastructure to scale production AI effectively.
What role does the "Ignition" agent play in Infinity's optimization process?
Ignition is an autonomous AI research agent that writes, tests, and optimizes the low-level compute kernels required for a chip to run AI models efficiently, aiming to compress the software development cycle from years into days.
Source: Infinity